Using Python in RevOps: How to Update Your CRM and Avoid Duplicates
A real case: 30,000 new accounts against a CRM with 10,000, brand names on one side and legal names on the other. The Python script we use to match them before import, updated for 2026 with RapidFuzz, name normalisation, a review band and a safe-merge checklist.
 Haris Odobasic
Share article
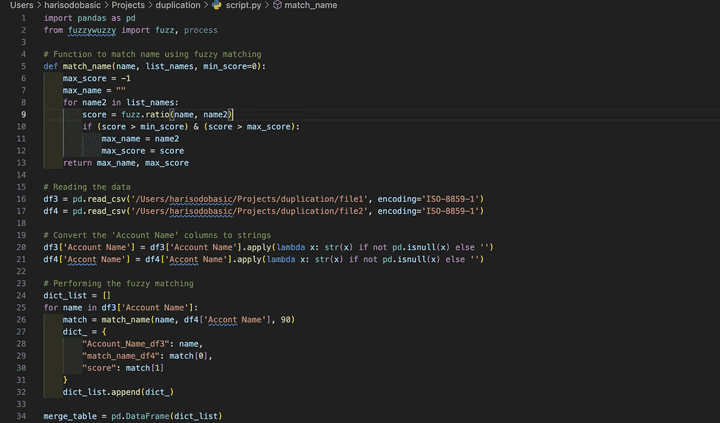
To update a CRM without creating duplicates, match every new record against what is already in the CRM before you import, then import the matches as updates using the CRM record ID. When company names do not match exactly, a short Python script with fuzzy matching (pandas plus RapidFuzz) does this for tens of thousands of rows in under a minute.
Python can be helpful in Revenue Operations. I like to use it when I have to handle data. This is also what GTM engineering looks like day to day. It is a small, specific tool that removes a manual job and protects the data every report, forecast and AI agent reads.
Why matching 30k accounts against a CRM breaks spreadsheets
We recently had to match a list of 30k accounts against a CRM that already had 10k accounts. You can bet there were tons of duplicates.
The main issue was that the CRM often used the brand name (The Lego Group) while the new file had only legal names (Lego A/S). Bummer.
That means comparing 300 million possible pairs. It crashes spreadsheet tools like Excel or Google Sheets (at least, it did for me).
Tip: Before importing any data into the CRM, make sure your data set is in the best possible shape. Once it is in the CRM, corrections become far more time-consuming (and expensive). A quick self-check like our RevOps data assessment shows where you stand.
Why use Python and AI for CRM data matching
Let me guess. Python sounds intimidating? I thought the same. My coding is far from perfect. Today it is easier to learn than ever, and AI assistants such as ChatGPT are a game changer. In a few months you can learn enough to use it for business cases like fuzzy matching. Our AI playbook for sales and RevOps covers where else AI pays off.
How fuzzy matching finds duplicate company names
You need the two files you want to match, which in our case were these.
- File 1 is the export from the CRM, including the record ID.
- File 2 is the new data from the data provider.
Tip: Make sure there are no duplicates within each file. The script warns you if it finds any.
Matching variable. Each file needs a column to match on. In our example both have a column called "Account Name". If the column names differ between files, you set each one separately when you run the script.
Fuzzy matching. Fuzzy matching is a method for approximately matching strings. In plain English, it matches similar words, like in the picture below.
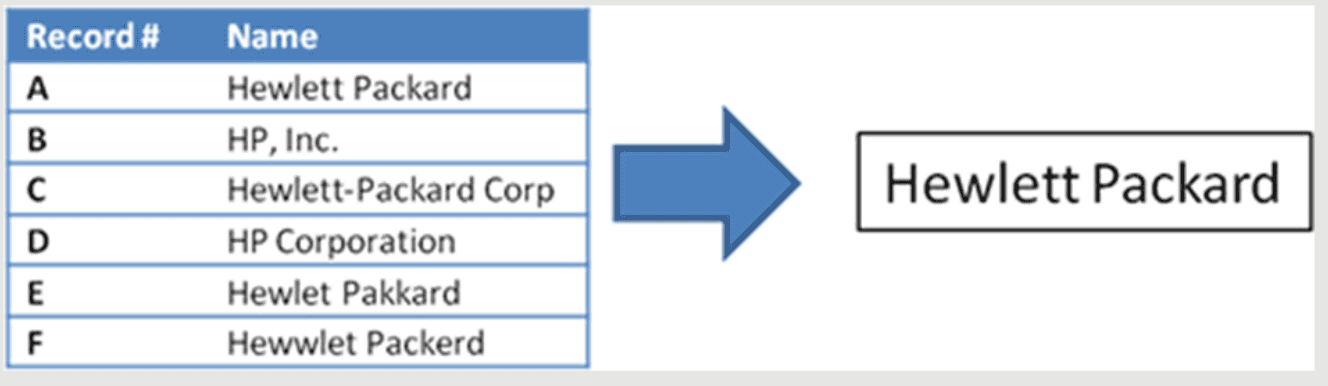
Here is a detailed explanation of the concept.
For our purposes, you only need to know that a fuzzy match needs a similarity threshold. The percentage tells the script how similar two names must be to count as a match.
- Too high, for example 97%, and you miss real matches.
- Too low, for example 84%, and you get more wrong matches.
A good practice is 90 to 95%. The script uses 90 for a match and treats 80 to 90 as "review", so a human looks at the borderline cases instead of the script guessing.
You can go below 90, but then do a few test runs and check the results manually for odd matches. It all depends on your source data.
Normalise first. Before comparing, the script lowercases names, strips punctuation and drops legal forms and filler words (Ltd, GmbH, B.V., A/S, Group, The). This step does most of the work. Since version 3.0, RapidFuzz no longer preprocesses strings by default, so the script does it explicitly.
Here is what that looks like on the names in the picture, run through the script against one CRM record called "Hewlett Packard".
| New name | Score | Status |
|---|---|---|
| Hewlett-Packard Corp | 100 | match |
| Hewlet Pakkard | 89.7 | review |
| Hewwlet Packerd | 86.7 | review |
| HP, Inc. | no match | new |
| HP Corporation | no match | new |
Fuzzy matching catches typos and legal suffixes. It does not know that HP and Hewlett Packard are the same company. That is what domains are for.
Which fields to match on to avoid duplicate records
| Match on | Strength | Notes |
|---|---|---|
| Website domain | Strongest | HubSpot itself deduplicates companies by domain name and contacts by email address |
| Company registration or VAT number | Strong | Reliable when your data provider supplies it |
| Normalised name plus country | Good | What this script does; add country to separate same-name companies |
| Name only | Weakest | Use the review band and check by hand |
Full Python script for fuzzy matching CRM accounts
You only need to set a few options when you run it.
- the two file paths
- the matching column in each file ("Account Name" by default)
- the CRM record ID column ("Record ID" by default)
- the match threshold and the review floor (90 and 80 by default)
Install the two libraries once with pip install pandas rapidfuzz, then run the script below.
python match_accounts.py crm_accounts.csv new_accounts.csv --crm-column "Account Name" --new-column "Account Name"
The script writes matches.csv with one row per new account, showing the best CRM match, its record ID, the score and a status of match, review or new.
"""Match a new account list against your CRM before import, so you update instead of duplicating.

Usage:
    python match_accounts.py crm_accounts.csv new_accounts.csv \
        --crm-column "Account Name" --new-column "Account Name" \
        --crm-id-column "Record ID" --threshold 90 --review-floor 80

Output: matches.csv with one row per new account and a status column:
    match  = score >= threshold: update the existing CRM record (use its record ID)
    review = score between review-floor and threshold: a human decides
    new    = no good match: import as a new record
"""
import argparse
import re

import pandas as pd
from rapidfuzz import fuzz, process, utils

DROP_TOKENS = {  # legal forms and filler words that make the same company look different
    # extend this set for the countries you sell into
    "the", "inc", "ltd", "llc", "plc", "corp", "corporation", "co", "company",
    "limited", "group", "holding", "holdings", "gmbh", "ag", "bv", "nv",
    "sa", "sas", "srl", "spa", "as", "aps", "ab", "oy", "kg",
}


def normalise(name):
    """Lowercase, strip punctuation and legal forms: 'Lego A/S' and 'The LEGO Group' both become 'lego'."""
    if pd.isna(name):
        return ""
    tokens = utils.default_process(str(name)).split()
    merged, letters = [], ""
    for token in tokens:  # glue initials back together: 'b v' -> 'bv', 'a s' -> 'as'
        if len(token) == 1:
            letters += token
            continue
        if letters:
            merged.append(letters)
            letters = ""
        merged.append(token)
    if letters:
        merged.append(letters)
    kept = [t for t in merged if t not in DROP_TOKENS]
    return " ".join(kept) if kept else " ".join(merged)


def main():
    parser = argparse.ArgumentParser(description=__doc__, formatter_class=argparse.RawDescriptionHelpFormatter)
    parser.add_argument("crm_file", help="CSV export from your CRM (must include the record ID)")
    parser.add_argument("new_file", help="CSV with the new accounts you want to import")
    parser.add_argument("--crm-column", default="Account Name")
    parser.add_argument("--new-column", default="Account Name")
    parser.add_argument("--crm-id-column", default="Record ID")
    parser.add_argument("--threshold", type=float, default=90)
    parser.add_argument("--review-floor", type=float, default=80)
    parser.add_argument("--encoding", default="utf-8-sig", help="try ISO-8859-1 if the export has odd characters")
    parser.add_argument("--out", default="matches.csv")
    args = parser.parse_args()

    crm = pd.read_csv(args.crm_file, encoding=args.encoding, dtype=str)
    new = pd.read_csv(args.new_file, encoding=args.encoding, dtype=str)
    for df, col, label in ((crm, args.crm_column, "CRM file"), (new, args.new_column, "new file")):
        if col not in df.columns:
            raise SystemExit(f"Column '{col}' not found in the {label}. Columns: {list(df.columns)}")

    crm["_key"] = crm[args.crm_column].map(normalise)
    new["_key"] = new[args.new_column].map(normalise)

    # Duplicates inside each file come first: fix them before matching across files.
    for df, label in ((crm, "CRM file"), (new, "new file")):
        dupes = df[df["_key"].ne("") & df.duplicated("_key", keep=False)]
        if len(dupes):
            print(f"Warning: {len(dupes)} rows in the {label} share a normalised name with another row.")

    choices = crm["_key"].tolist()
    rows = []
    for _, record in new.iterrows():
        best = None
        if record["_key"]:
            # extractOne runs in C++ and stops early below score_cutoff
            best = process.extractOne(record["_key"], choices, scorer=fuzz.token_sort_ratio,
                                      score_cutoff=args.review_floor)
        if best:
            _, score, position = best
            status = "match" if score >= args.threshold else "review"
            crm_name = crm.at[position, args.crm_column]
            crm_id = crm.at[position, args.crm_id_column] if args.crm_id_column in crm.columns else ""
        else:
            score, status, crm_name, crm_id = 0, "new", "", ""
        rows.append({
            "new_name": record[args.new_column],
            "crm_match": crm_name,
            "crm_record_id": crm_id,
            "score": round(score, 1),
            "status": status,
        })

    result = pd.DataFrame(rows)
    result.to_csv(args.out, index=False)
    print(result["status"].value_counts().to_string())
    print(f"Saved {len(result)} rows to {args.out}")


if __name__ == "__main__":
    main()
A few things changed from the 2023 version. The column-name typo is gone (each file's column is an option), there is no hard-coded file path, fuzzywuzzy is replaced by RapidFuzz, names are normalised, borderline scores go to review, and every match carries the CRM record ID.
Why the old fuzzy matching script was slow
The 2023 script compared every new name with every CRM name in a pure-Python loop. That is 30,000 times 10,000, or 300 million comparisons, each one a Python function call. That is why it took minutes.
The new version hands the inner loop to RapidFuzz's process.extractOne, which runs in C++ and skips candidates that cannot reach the cut-off score. In our test with 30,000 synthetic company names against 10,000, it finished in 37 seconds on a laptop, on a single core.
For much bigger lists, cut the comparisons rather than speeding them up. Only compare names that share a country, a first letter or a domain (a technique called blocking), or use RapidFuzz's process.cdist with multiple workers.
Checklist for safely merging duplicates in your CRM
Matching is the easy part. Updating the CRM without losing good data takes discipline.
- Export a full backup of the affected objects before you change anything, and treat merges as irreversible.
- Never auto-merge. Review every row in the review band, and spot-check the match band.
- Import matches as updates using the CRM record ID; in HubSpot, the Record ID (or the company domain name for companies) is the unique identifier that updates existing records instead of creating new ones.
- When two CRM records are duplicates, keep the one other systems sync with as the primary. With HubSpot and Salesforce, that is the record currently syncing, as we explain in our HubSpot and Salesforce integration guide.
- Import parent records before children, and keep a mapping of old to new IDs.
- Run the match again after the import to confirm nothing new slipped in.
In client CRMs, duplicates rarely stay a cosmetic problem, because contacts and deals end up linked to the wrong account, or to none, and every roll-up inherits the error. If you run HubSpot and the duplicates keep coming back, our CRM Health Check finds the forms, imports and integrations that create them. The one fix we build can be a deduplication tool like this one, flagging likely duplicates for review based on rules you choose.
When to use a deduplication tool instead of a script
- Ongoing prevention belongs in the CRM. Salesforce matching rules find likely duplicates and duplicate rules block them or warn the user; HubSpot deduplicates contacts by email and companies by domain automatically. Switch these on first.
- Bulk imports and messy names suit a script. Brand names against legal names, provider lists without domains and one-off migrations are where this script earns its keep.
- Do not deduplicate with workflow tools. Zapier or Make automations have no built-in deduplication and can create duplicates themselves.
- Buy when it becomes a job. If you dedupe every week across several objects, a dedicated tool may beat maintaining a script. Our build vs buy guide helps you decide.
I hope this was helpful. It saved me countless hours of work and an investment in a tool to solve the problem. If your duplicate problem is bigger than one import, start with our CRM Health Check.
Frequently asked questions about CRM deduplication with Python
What is fuzzy matching?
Fuzzy matching compares strings by similarity instead of exact equality, so "Hewlet Pakkard" can still match "Hewlett Packard". It returns a score, usually 0 to 100, and you choose the threshold that counts as a match.
What fuzzy matching threshold should I use for company names?
Start at 90 for a match and send 80 to 90 to manual review. Higher thresholds miss real matches; lower ones create wrong matches. Test on a sample of your own data first.
Why use RapidFuzz instead of fuzzywuzzy?
fuzzywuzzy was renamed to thefuzz and its original repository was archived in August 2024. RapidFuzz uses the same similarity calculations, is much faster and has an MIT licence. It is largely a drop-in replacement, but from version 3.0 it does not preprocess strings by default.
Can this script merge duplicates automatically?
No, by design. It matches and labels each row as match, review or new. You then import matches as updates using the CRM record ID and merge true duplicates in the CRM after a human check, because merges are hard or impossible to undo.
How do I update existing CRM records instead of creating new ones?
Include a unique identifier in the import file. In HubSpot that is the Record ID, or the company domain name for companies; without one, imports create duplicates instead of updating. That is why the script returns the CRM record ID for every match.